Move beyond brittle toy prototypes. We design, deploy, and evaluate resilient cognitive systems: autonomous multi-agent loops, grounded hybrid vector retrieval, and private on-prem SLMs engineered for zero data exfiltration.
Building a proof-of-concept in a notebook is trivial. Running mission-critical AI in production requires overcoming ungrounded hallucinations, runaway inference bills, and catastrophic data leaks.
Without citation-grounded retrieval and deterministic validation, models confidently fabricate financial figures, contractual clauses, and inventory quantities that cause severe business liability.
Streaming sensitive proprietary source code, executive emails, or customer PII into public foundation model APIs risks non-compliance with GDPR, HIPAA, and SOC-2 mandates.
Naive multi-turn prompt chains send 15,000 tokens of context on every turn, triggering 4,000ms latency spikes and surprise five-figure monthly cloud model bills.
Unstructured free-form text generations fail randomly when parsed by downstream backend microservices, causing silent database errors and workflow crashes.
We architect custom cognitive workflows designed around your data topology, compliance requirements, and latency SLAs.
Orchestrate collaborative teams of specialized agents with shared state, episodic memory, and reflection loops to handle multi-step workflows without human intervention.
Connect foundation models directly to your unstructured documents, Notion, databases, and ERPs with dense semantic embeddings and keyword-exact BM25 search.
Achieve 100% data sovereign operations. We fine-tune and serve high-efficiency open-source models (Llama 3.1, Mistral, Qwen) directly on your dedicated hardware or private cloud.
Bridge natural language intent to concrete transactional operations. Models safely execute sandboxed SQL queries, invoke REST APIs, and trigger backend workflows with mathematical schema validation.
Vendor-agnostic architecture. We integrate the best-in-class foundation models, specialized vector engines, and high-concurrency inference runtimes.
Running enterprise LLMs without rigorous systems engineering leads to downtime and unmanageable invoices. Here is how we enforce control.
Why query expensive frontier models for semantically identical questions? We implement sub-15ms vector caches in Redis that recognize paraphrased user intents, instantly returning pre-computed answers and slashing API token bills by up to 60%.
-60% API Token CostNot every task requires a 400B parameter reasoning model. Our routing gateway classifies prompts in real-time, directing simple classification and entity extraction to rapid 8B SLMs, reserving frontier models strictly for complex multi-turn problem-solving.
< 180ms Median TTFTWhen an agentic workflow prepares to execute high-impact actions—such as processing customer refunds, mutating financial ledgers, or triggering external webhooks—the system enforces human-in-the-loop sign-off whenever confidence falls below 95%.
Zero Destructive ErrorsSystem prompts drift over time. We establish synthetic evaluation suites with Ragas and DeepEval that run in your CI/CD pipelines before any prompt or retrieval update is deployed to production, ensuring zero accuracy regression.
Automated CI/CD BenchmarksProtect your intellectual property, customer trust, and regulatory posture with multi-layered containment firewalls.
Commercial enterprise model agreements explicitly barring model providers from storing, training on, or inspecting your prompt streams.
Deterministic Named Entity Recognition (NER) and regex layers scrub social security numbers, API secrets, and patient identifiers prior to model transit.
Active barrier models (NeMo Guardrails & LlamaGuard) inspecting all incoming context for adversarial jailbreaks and indirect injection attempts.
Deploy vector databases and serving runtimes entirely inside single-tenant AWS/Azure GovCloud VPCs with strict zero-trust ingress control.
We build high-performance digital products and platforms that drive real commercial results.
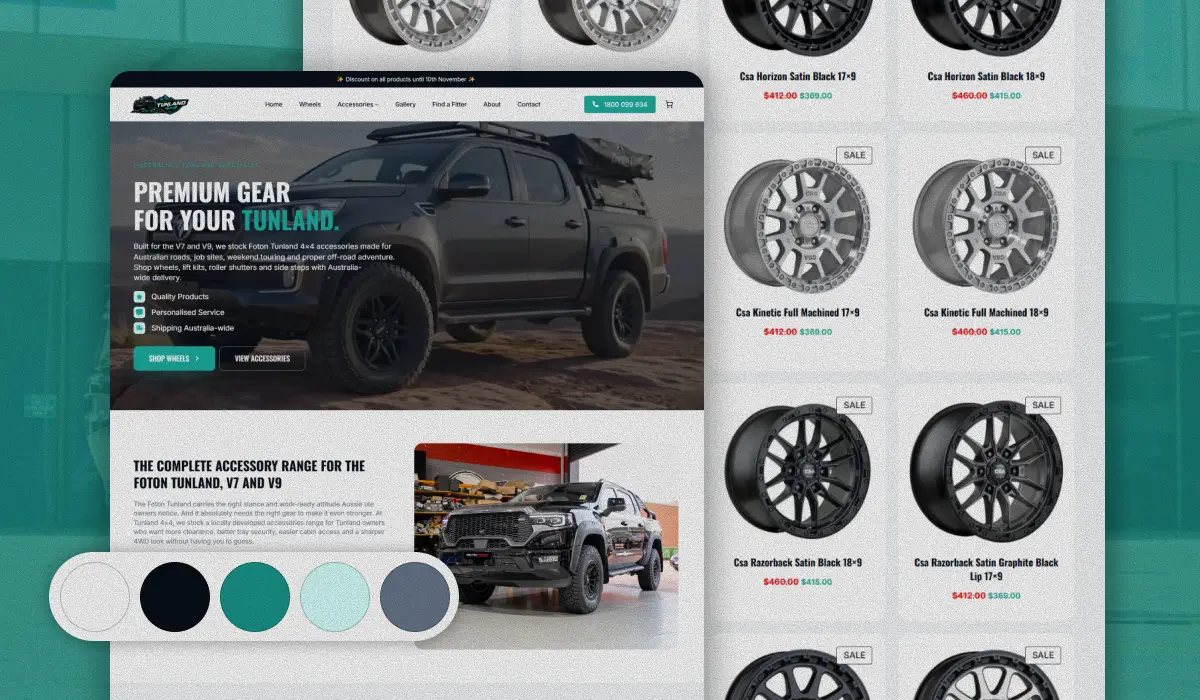
Dedicated 4WD e-commerce platform for Foton Tunland utes built from scratch on WordPress with model-specific fitment verification, dynamic suspension catalogs, and sub-second speed.
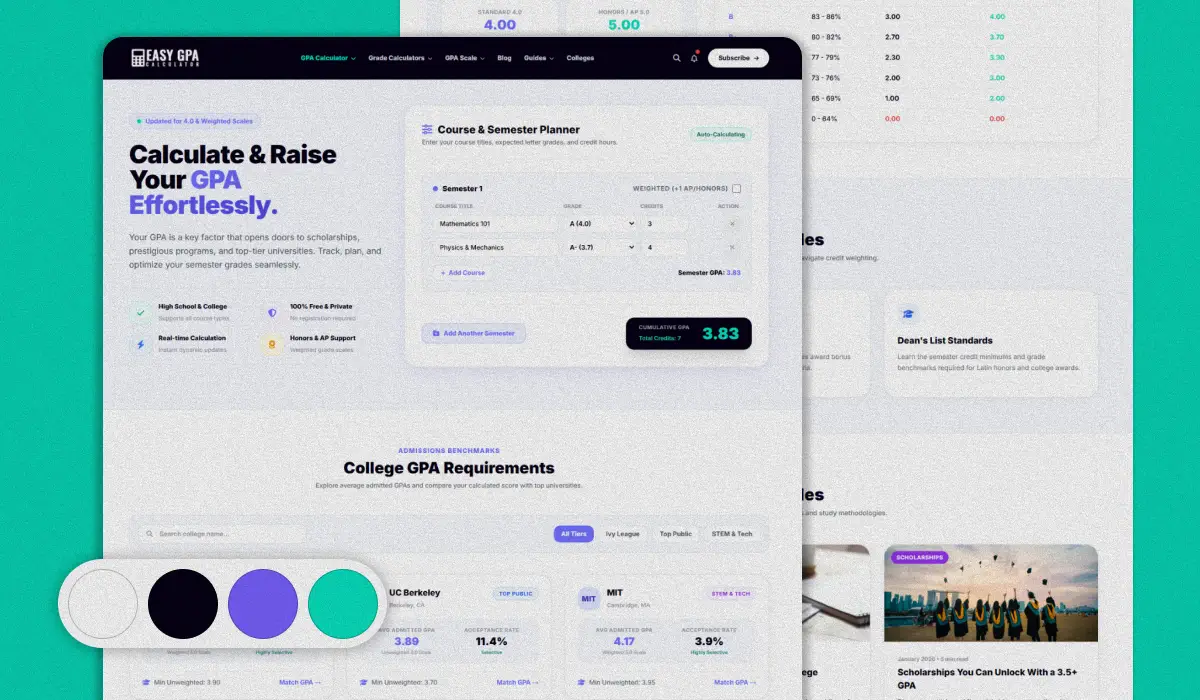
Startup calculation tool and college guide platform for students, re-engineered on WordPress with an in-memory computation engine and full programmatic SEO architecture.
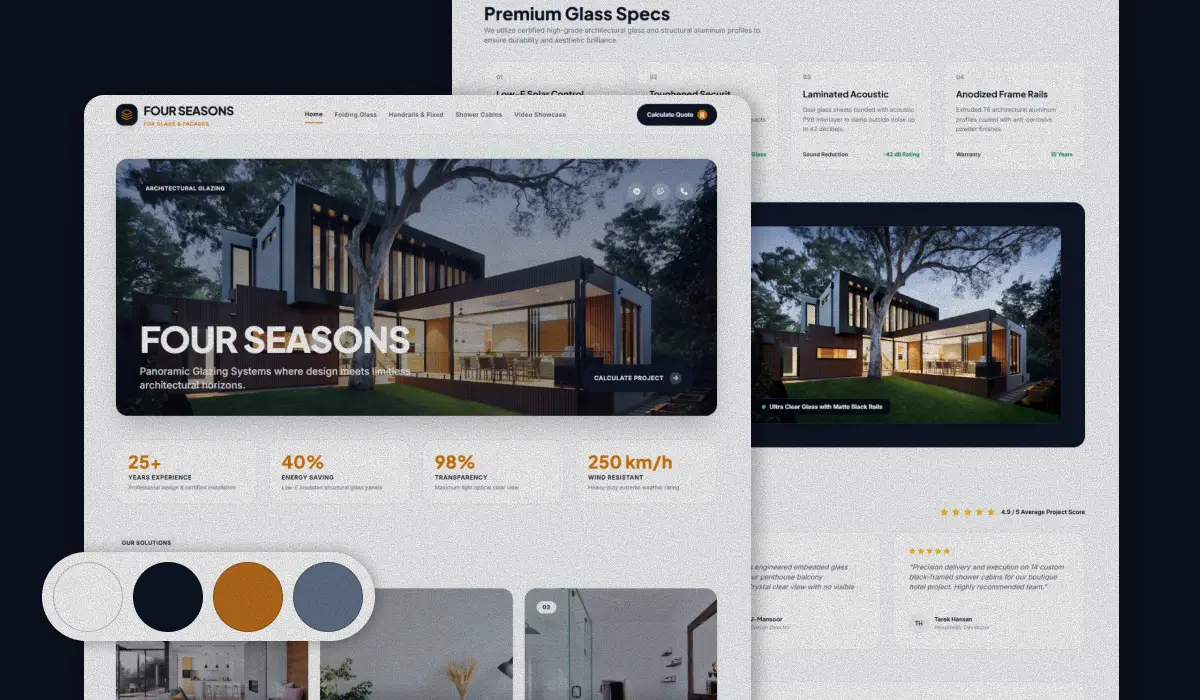
Bespoke custom WordPress platform engineered from scratch for Egypt’s premier architectural glazing fabricator, featuring next-gen WebP portfolio galleries and localized regional SEO.
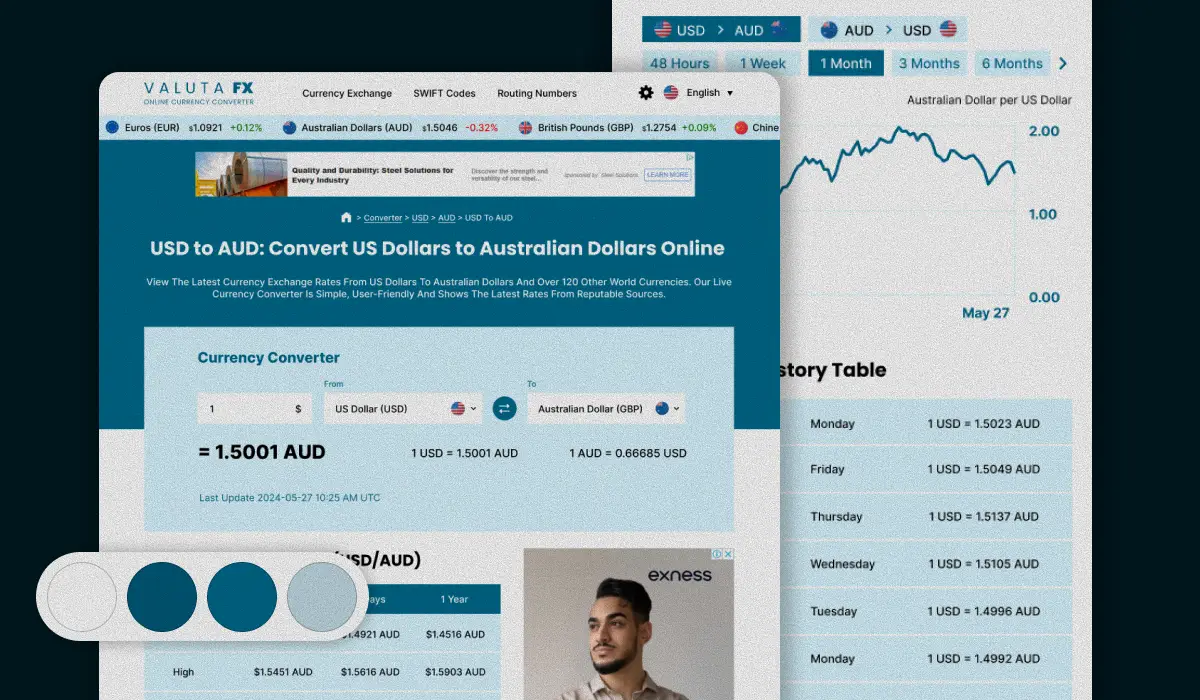
End-to-end UI/UX redesign and logo modernization for a high-traffic global currency converter, engineered with high-contrast fintech components and streamlined conversion flow.
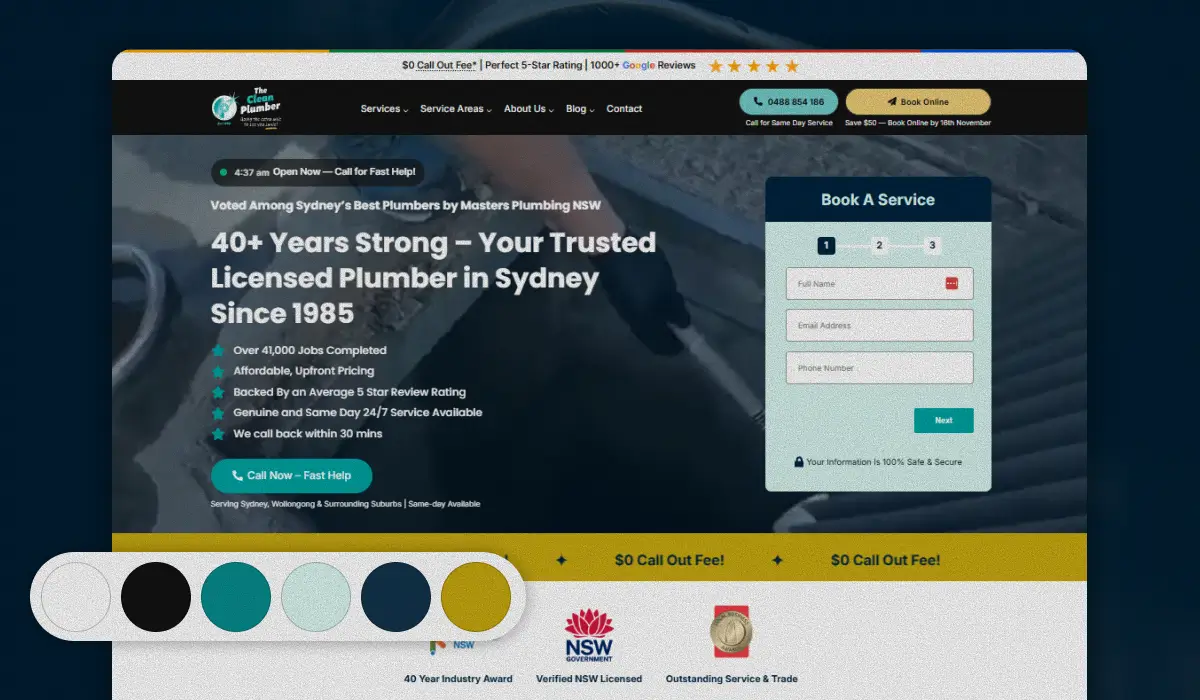
Full digital redesign for Sydney and Illawarra's premier plumbing specialists, engineered for sub-second mobile speed, friction-free booking forms, and high-converting local outreach.
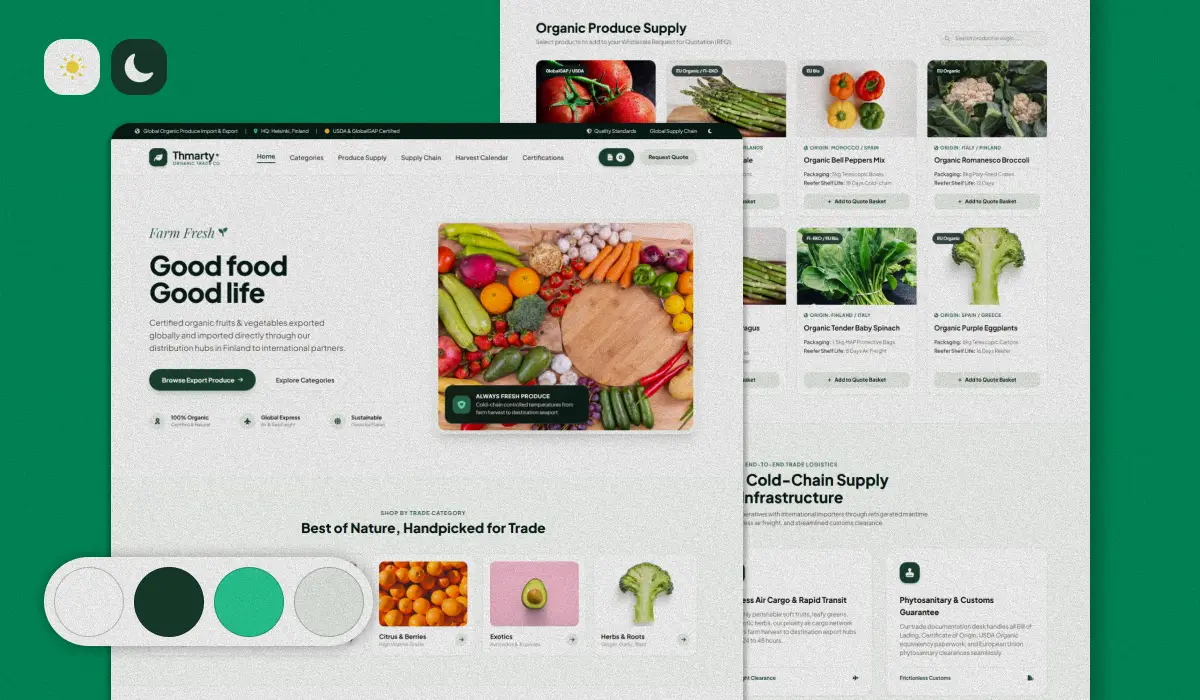
High-performance international trading portal for certified organic vegetables and fruits, featuring wholesale container specifications, EU compliance certifications, and automated B2B RFQs.
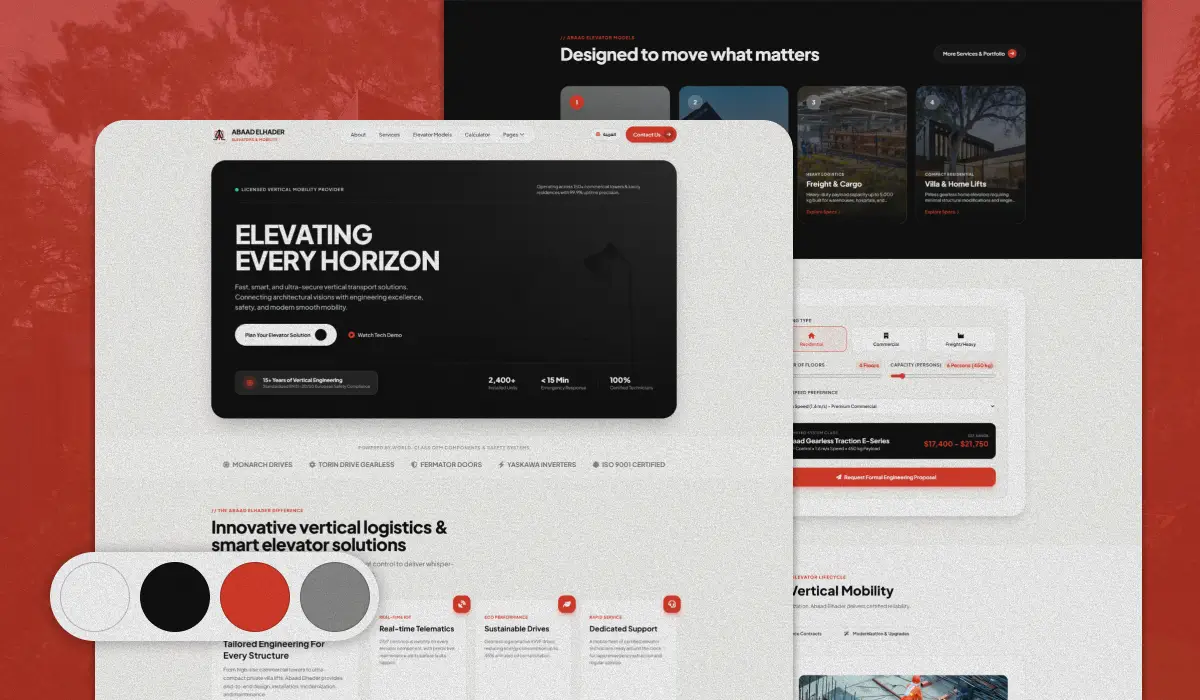
Modern corporate digital presence for an architectural elevator and mobility engineering leader, featuring interactive lift configurators, technical specifications, and luxury project showcases.
Trusted by clients who value quality and results.
"The Tunland 4x4 website has already made its first sale! We're so happy with the results. Thank you for all your help and support. Alaa did an amazing job bringing the vision and direction to life."
"Working with Code1001 made a huge difference for my clinic. The website is clean, loads fast, and patients find it very easy to book their sessions online. Alaa really listened to what we needed and delivered ahead of schedule."
"We're getting a lot of compliments on the new website, and we already received several quote requests through WhatsApp in the first week. Alaa was super helpful, patient, and delivered exactly what we asked for. Thank you so much!"
"Managing my student groups and teaching schedule used to take up hours of paperwork every week. Abdelrahman from the Code1001 team built a custom app that organized everything—classes, timings, and student tracking—in one simple place. It made my daily work so much easier. Thank you so much Abdelrahman and the Code1001 team!"
"Code1001 helped us take Step Up Academy to the next level. They created beautiful designs for our brand and automated our student registrations and daily follow-ups. What used to take hours of manual work every day now runs smoothly. Thank you so much for the wonderful work and continuous support!"
Clear, pragmatic answers to the questions enterprise architects ask when evaluating production GenAI and LLM deployments.
We architect workflows using enterprise-tier APIs (OpenAI Enterprise, Azure OpenAI, Anthropic Bedrock) that contractually enforce Zero Data Retention (ZDR), meaning your prompts, retrieved documents, and outputs are never stored or used in fine-tuning. For regulated industries (FinTech, Healthcare, Defense), we deploy open-source models (such as Llama 3.1 or Mistral) entirely within your private VPC or on-prem DGX cluster, creating complete physical and network isolation from external servers.
RAG (Retrieval-Augmented Generation) is like giving an open book to an intelligent researcher: it provides up-to-the-minute facts, policies, and documents at query time with verifiable citations. Fine-Tuning is like teaching a doctor specialized bedside manner: it modifies the model's tone, structure, or specialized vocabulary (e.g., proprietary syntax or medical codes). Most enterprise architectures start with Hybrid RAG for real-time fact retrieval, and layer parameter-efficient fine-tuning (LoRA) only when specialized formatting or domain jargon requires it.
We utilize automated ground-truth evaluation frameworks (Ragas and DeepEval) that score three distinct metrics on every response: Faithfulness (is the answer mathematically supported by retrieved context?), Context Precision (did the retrieval contain noise?), and Answer Relevancy. If the calculated faithfulness score falls below the required threshold (typically 0.95), the system automatically triggers a secondary retrieval pass or gracefully escalates to a human fallback instead of outputting an ungrounded hallucination.
We eliminate cost unpredictability through three architectural safeguards: (1) Semantic caching in Redis, which absorbs up to 60% of repetitive prompts without calling LLM endpoints; (2) Cascaded model routing that directs 70% of standard tasks to low-cost 8B SLMs costing pennies per million tokens; and (3) Hard token rate limiters and departmental budget quotas that alert engineers well before monthly caps are reached.
Yes. We architect self-hosted inference clusters using vLLM, TensorRT-LLM, and Ollama deployed on NVIDIA A100/H100/L40S hardware or local DGX workstations. The entire retrieval pipeline, embedding generation, vector indexing in Qdrant/pgvector, and model execution runs within an air-gapped local subnet with zero egress connectivity to public cloud providers.
A typical production engagement follows a structured 4-to-8 week rollout: Week 1-2 focuses on data profiling, embedding chunk selection, and security boundary alignment. Week 3-4 delivers a functional staging pipeline with automated eval benchmarks. Week 5-8 refines latency via semantic caching, establishes human-in-the-loop workflows, and conducts cutover testing with live telemetry.
Book an architecture consultation with our senior AI systems engineers. We will review your data pipelines, evaluate latency constraints, and outline a deterministic production blueprint.